The step from an agent demo to an agent in production is rarely held up by the model. A demo answers "can a model do this?". Production asks a harder question: should this agent do this, here, with these limits — and who answers for it when it goes wrong?
This playbook turns that question into seven decisions. Make them in order, write each one down, and you have the blueprint of a governed agent: something a business can test, approve, operate and improve. Skip one, and it returns later as an incident, an approval nobody can make, or an agent nobody owns.
The model: seven decisions
| # | Decision | The question | The artefact |
|---|---|---|---|
| 1 | Job | What work, for whom, what counts as done, what is never allowed? | Mission sheet |
| 2 | Evidence | What does the agent work from, and what does it leave behind? | Source and record map |
| 3 | Tools | Which systems may it use? | Tool allowlist |
| 4 | Permissions | What may it do in each, within which limits? | Permission matrix |
| 5 | Escalation | When does it stop and hand over to a person? | Escalation rules and approval routes |
| 6 | Evaluation | How do we know it is ready — and still ready? | Scorecard and thresholds |
| 7 | Operating owner | Who answers for it in production? | Owner card and runbook |
The order matters. Tools follow from the job; permissions narrow the tools; escalation covers what the permissions leave out; evaluation tests all of it; the owner accepts the result. Decide them out of order and you will be granting permissions for a job nobody has defined.
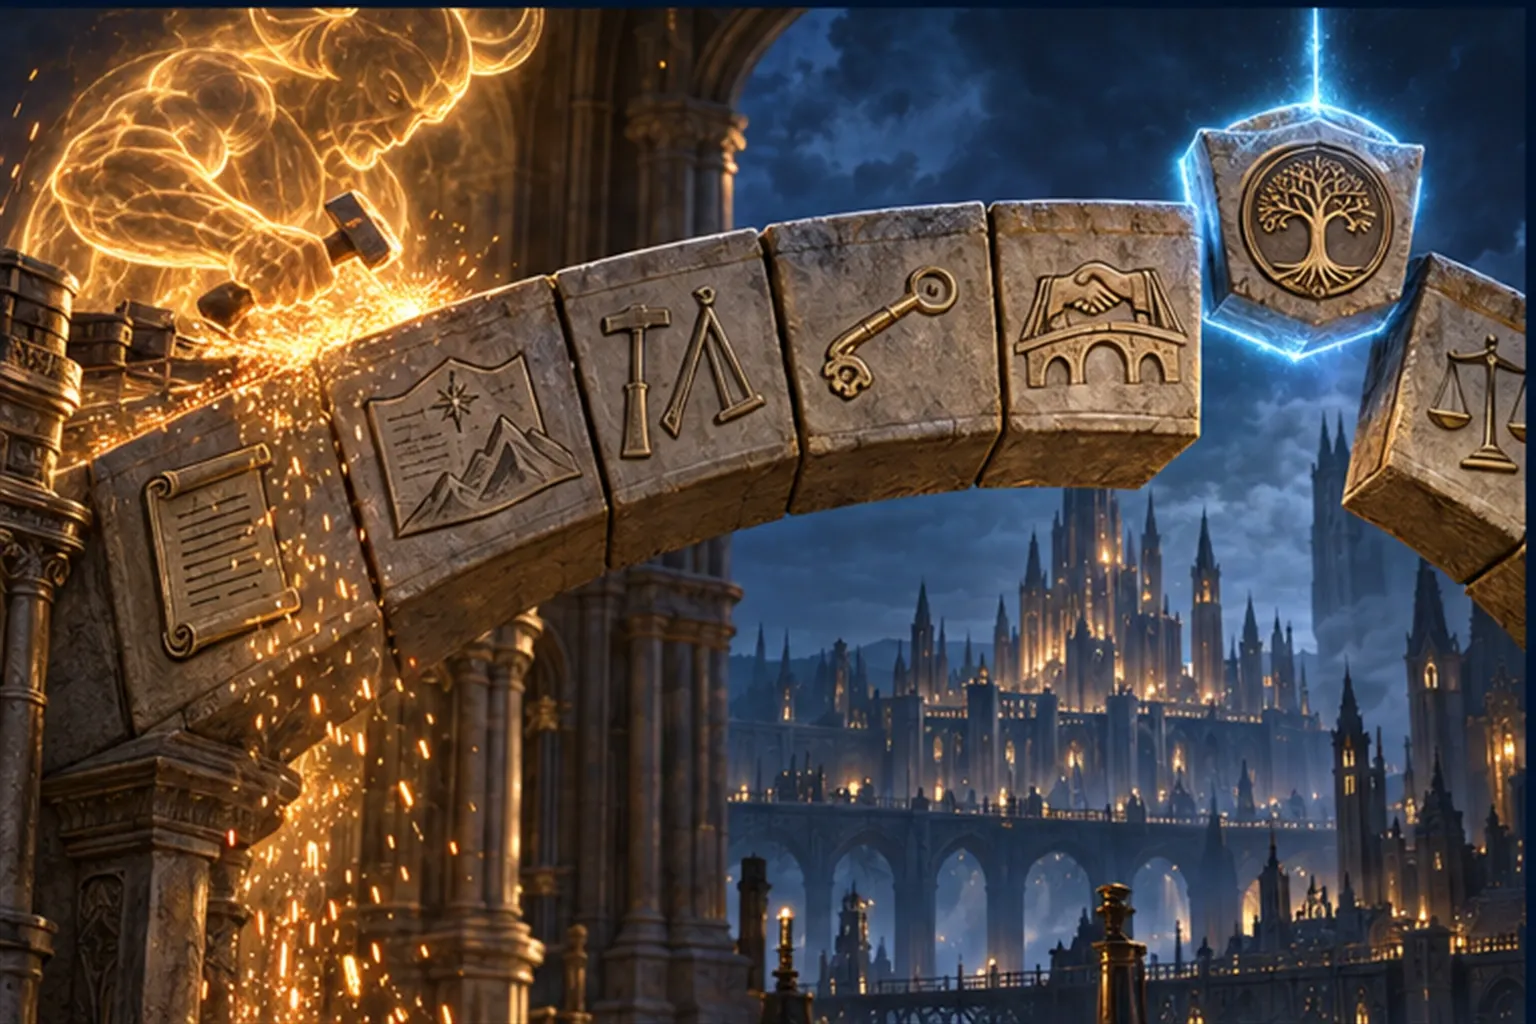
Public frameworks ask for the same things in other words. The NIST AI Risk Management Framework organises the work as Govern, Map, Measure and Manage — accountability, context, testing and ongoing management. OWASP traces "excessive agency" in LLM applications to excessive functionality, permissions and autonomy: decisions 3, 4 and 5.
Builders propose; the business decides. A blueprint signed only by engineers is a technical document, not a governed agent.
| Decision | Proposed by | Decided by |
|---|---|---|
| Job | The business owner of the workflow, with the builders | The operating owner |
| Evidence | The builders, with knowledge and data owners | Each source's owner |
| Tools | The builders | The owners of the systems involved |
| Permissions | The builders, with security | Security and the operating owner |
| Escalation | The operating owner | The people who will receive the escalations |
| Evaluation | The evaluators | A reviewer independent of the build |
| Operating owner | Leadership | The owner, by accepting |
In the Guild the same split holds: Athena structures the mission, Hephaestus builds it, Sentinel protects its boundaries, Oracle owns the scorecard, and a Human Wizard remains accountable and makes the deployment decision.
The job
Describe work, not a persona. "A helpful finance assistant" is a persona. "Matches supplier invoices to purchase orders and schedules payment for those within tolerance" is a job, and it can be tested.
A good job definition is one workflow with one outcome, for a named group of users, with a definition of done and a short list of things the agent must never do — even if asked. Start with the smallest agent that can deliver a meaningful result, and expand only when the evidence supports it.
The common mistake: a job so broad that every request is in scope, so no request can be declined.
Evidence
Evidence has two halves.
What the agent works from. Approved knowledge — owned, current, permission-aware, cited (Field Guide 017). Live data, queried through tools rather than copied. And memory: what it may remember between interactions, for how long, about whom, and who can see it (How agent memory should work). An agent that remembers everything will eventually remember something it should not.
What it leaves behind. Every action recorded with its inputs, the sources it relied on, its reason and its result — enough that someone who was not there can reconstruct why it acted.
The common mistake: pointing the agent at a shared drive and calling it knowledge.
Tools
List the systems the agent may use. Everything else should not exist for it.
Make each tool narrow and named for its purpose — issue_refund(order, amount), not "call any API". Separate tools that read from tools that change things. Make write tools safe to retry, so that a timeout does not become a second payment. And make sure every tool can run in a test environment, or you will be testing in production.
The common mistake: open-ended tools — raw database queries, arbitrary web requests, a shell — added "for flexibility". Flexibility is what you are trying to remove.
Permissions
For every tool, decide the action (read, draft, change, delete), the data scope (whose records, which fields) and the limits (amounts, volumes, rates, time windows). The agent acts under its own identity, never a person's, and every permission can be revoked in one step.
Then decide where it starts on the autonomy scale. The Citadel's trust model has four levels — Observe, Assist, Operate, Optimize — and a new agent should start at the lowest level that is still useful, usually Observe (it recommends, a person acts) or Assist (it prepares, a person approves). How it moves up is the subject of The Citadel Trust Model.
The common mistake: permissions granted to make the demo work, and never removed.
Escalation
Write down the conditions under which the agent stops and hands over:
- the action is above a limit, or cannot be undone;
- the evidence is missing, contradictory or outside what it was tested on;
- the request is an exception to policy;
- the topic is sensitive — a complaint, a legal threat, a vulnerable person;
- the person simply asks for a human.
Each condition routes to a named person with a backup, and the hand-over carries the context: what was asked, what the agent found, what it proposes. Field Guide 014 covers the approval patterns.
The common mistake: escalation to "the team", or a hand-over without context that has to be investigated from scratch.
Evaluation
Before the agent goes live, it is tested against the mission sheet: realistic scenarios from real work, including the cases that should make it stop; knowledge tests; tool tests in a sandbox. Thresholds are set before the first run. Policy and approval tests are must-pass — one failure means no-go; task success and knowledge are graded. A person reviews the evidence and signs go, go with conditions, or no-go.
Evaluation Kit 001 packages all of this. The decision you make here is narrower: which thresholds apply to this agent, who reviews, and what triggers a re-run — at a minimum, any change of model, instructions, tool or knowledge source.
The common mistake: evaluating once, at launch, and never again.
The operating owner
Name the person accountable for the agent in production. They watch its measures, review its exceptions, decide on changes to its autonomy, own its incidents, and can switch it off. Give them a runbook: how to pause the agent, how to take it back to a lower level, who to call, and when the next review is due.
The builder is rarely the right owner: projects end, agents keep running. In the Guild every deployed agent receives a named Human Wizard, and every engagement has a named Archmage and explicit Human Wizard checkpoints. An agent without an owner is an orphan, and orphans decay.
The common mistake: the owner field reads "IT".
The decision path and the canvas
Work through the questions in order. A "no" sends you back, not forward.
- Can you write the job in two sentences, with a definition of done? No → map the workflow first.
- Does every knowledge source have an owner? No → fix ownership before retrieval.
- Can every tool run in a test environment? No → build the test environment.
- Are the permissions narrower than the tools? No → narrow them.
- Does every escalation condition have a named person and a backup? No → name them.
- Has the agent passed its evaluation, with the result signed? No → fix, re-run, review.
- Has an operating owner accepted the agent and its runbook? No → it does not go live.
- All yes → deploy at the starting level, and expand on evidence.
Then fill in one page per agent and take it into the next working session.
| Field | Answer |
|---|---|
| Job · for whom · done means | |
| Never | |
| Works from (knowledge, data, memory) | |
| Leaves behind (records) | |
| Tools | |
| Permissions and limits | |
| Starting autonomy level | |
| Escalation conditions → person (backup) | |
| Must-pass tests · graded thresholds | |
| Re-evaluation triggers | |
| Operating owner · next review |
Example
Illustrative example, not a client engagement.
An online retailer wants an agent to handle return requests.
- Job: decide eligible returns and issue return labels for orders within the returns window; never issue refunds, never change addresses.
- Evidence: the returns policy (owned by customer service) and order data through the order system; no memory beyond the current conversation; every decision logged with the policy clause applied.
- Tools: order lookup (read), label generator (create), helpdesk reply (send).
- Permissions: only the orders of the customer in the conversation; a daily cap on labels.
- Escalation: outside the window, damaged goods, a third request from the same customer, any mention of legal action → the returns lead, with the order and conversation attached.
- Evaluation: scenarios from real return emails, including policy edge cases and attempts to talk the agent into a refund; policy and approval tests must pass.
- Owner: the customer service manager, with a monthly sample review and a runbook for pausing the agent.
It starts at Assist — the agent prepares the label and a person approves — and the owner decides whether in-window returns move to Operate once the samples support it.
Signs a decision was skipped
Agents in trouble usually show which decision was never made.
- Nobody can say whether a request is in scope — the job was never defined.
- Answers cite nothing, or cite last year's version — evidence was never decided.
- A permission request arrives in launch week — tools and permissions were left to the build.
- Mistakes are reported by customers, not raised by the agent — escalation was never designed.
- After a model upgrade, nobody knows whether it still works — evaluation was a one-off.
- Exceptions pile up with nobody assigned — there is no operating owner.
Each of these is cheaper to fix on the canvas than in production.
Checklist
- The job is one workflow, one outcome, with a definition of done and a "never" list.
- Every knowledge source has an owner; live data comes through tools.
- Memory is decided: what, how long, about whom, visible to whom.
- Every action leaves a record that explains it.
- Tools are narrow, purpose-named, safe to retry and testable.
- Permissions set action, data scope and limits; the agent has its own identity.
- The starting autonomy level is the lowest useful one.
- Every escalation condition has a named person, a backup and a context package.
- Thresholds are set before testing; must-pass tests are identified.
- Re-evaluation triggers are written down.
- A named operating owner has accepted the agent and its runbook.
