This guide is for teams that want AI agents to answer from their own organisation's knowledge — accurately, with sources, and without showing anyone what they should not see. It follows the Guild's twelve-chapter format: the problem first, the checklist last.
The problem
An agent can only be as good as what it is allowed to read. Without a knowledge system, it has two options, and both are bad. It answers from the model's general training, which knows nothing about your prices, policies or customers. Or it is handed a folder of documents and left to sort them out, which works in a demo and fails in the second month.
The failures are predictable: answers based on last year's policy, two documents that contradict each other with no way to tell which is current, a summary that quietly includes a figure from a file the user was never meant to see, and no way to check where any of it came from. Each one erodes trust, and trust is the only thing that lets an agent do real work.
Concept overview
A production knowledge system is a governed pipeline from approved sources to an agent's context. Five properties make it production-grade:
- Ownership — every source has a person responsible for its accuracy.
- Freshness — changes reach the agent quickly, and stale content is retired.
- Permissions — the agent retrieves only what the person it is serving may see.
- Citations — every answer points to the passage it came from.
- Feedback — wrong or missing answers flow back to the owners.
Keep three things apart. Knowledge is approved, owned content: policies, procedures, product information. Data is operational records — orders, tickets, balances — which an agent should query through a tool, not retrieve as text. Memory is what an agent keeps from its own interactions. They need different designs, and mixing them is a common source of error; Memory is not a database covers the difference in depth.
When to use this
Build a knowledge system when answers must come from your own material, that material lives in more than one place, it changes, different people may see different parts of it, and you need to show where an answer came from.
Do not build one when the question set is small and stable (a well-written FAQ may be enough), when the answer is a live number (use a tool that queries the system of record), or when nobody owns the content. In the last case, fix ownership first; retrieval will only make the disorder faster.
Architecture
A production knowledge system connects your content, data and operational context to AI agents through a layered architecture designed for accuracy, traceability and continuous improvement.
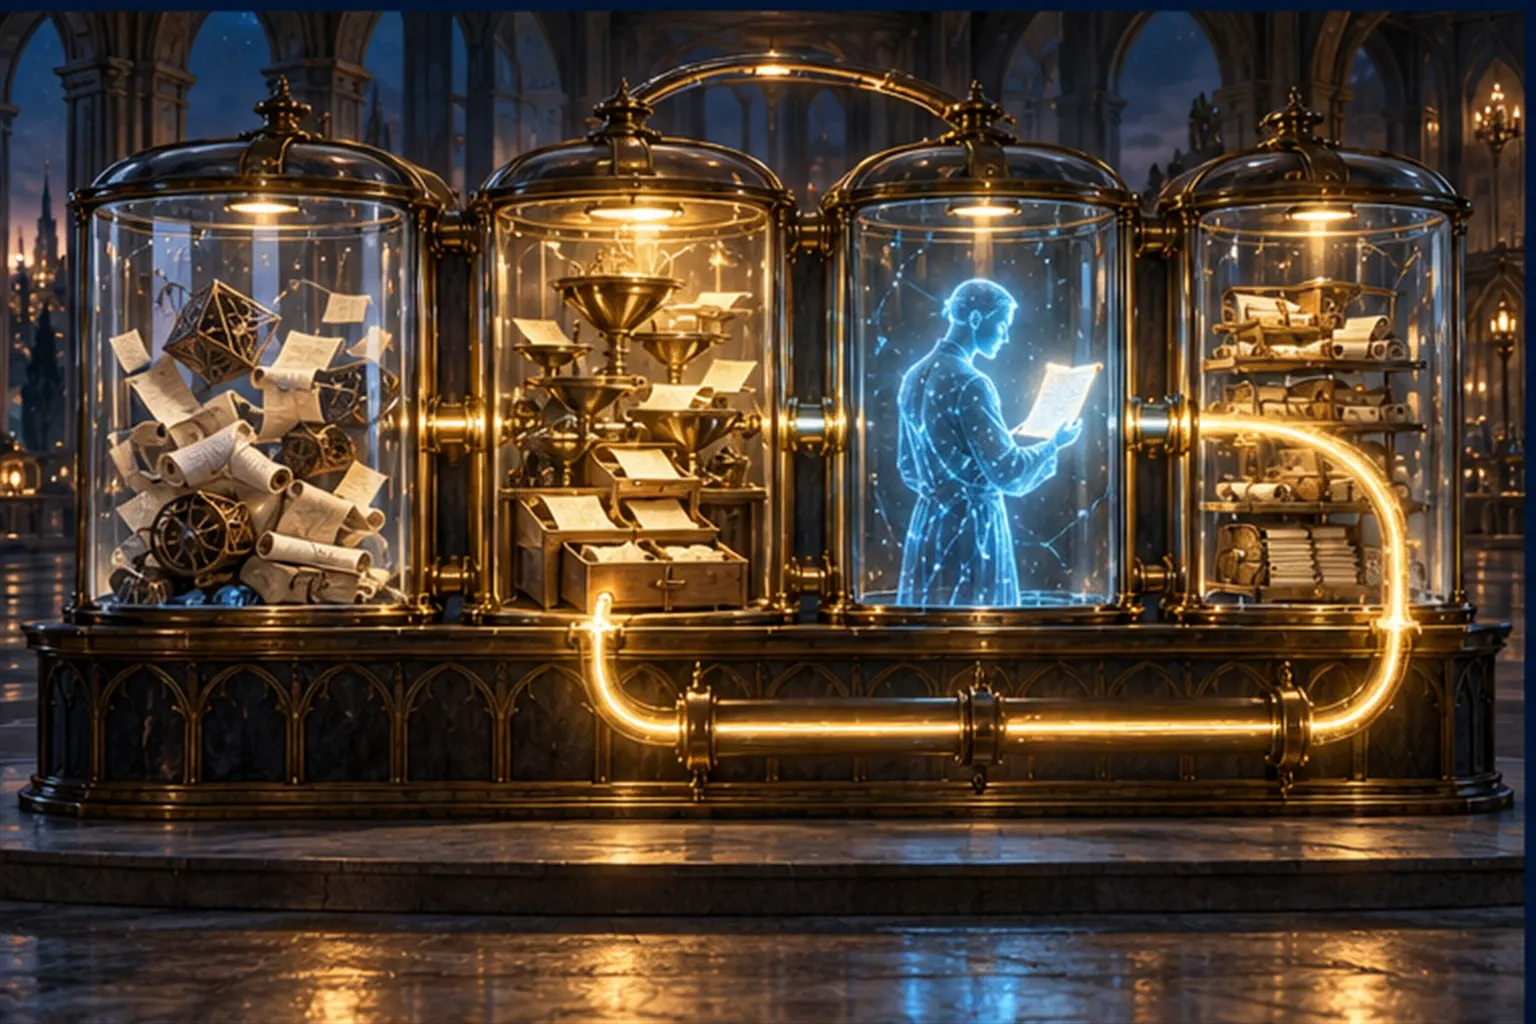
| Data sources | Knowledge layer | Agent access | Usage & feedback |
|---|---|---|---|
| Documents, databases, applications, web content, real-time data | Ingestion; chunking & enrichment; vector + graph storage; metadata & permissions | AI agents, through retrieval (RAG) and knowledge access | Agent responses, citations, user feedback, evaluation metrics, improvement |
Four principles hold the layers together:
- Modular — independent components that can evolve separately.
- Observable — full visibility into retrieval, usage and performance.
- Secure by design — access controls and data governance at every layer.
- Iterative — continuous improvement through evaluation and feedback.
Atlas note — A knowledge system is not a database with a vector index. It is a living system that connects your organisation's knowledge with the operational context where decisions are made.
Core components
Several components work together to deliver accurate, relevant and trustworthy information to AI agents.
Data ingestion
Connect to your content sources and continuously ingest, normalise and prepare data for your knowledge system.
- Multi-source connectors (APIs, databases, documents, web)
- Incremental updates and change detection
- Content classification and metadata extraction
- Data quality validation and deduplication
Chunking and enrichment
Split content along its own structure — sections, clauses, steps, table rows — rather than at a fixed character count. Keep each chunk's heading path, source, owner, effective date and sensitivity with it. A chunk that has lost its heading has lost half its meaning.
Storage and indexing
Use more than one index. Vector search finds passages that mean the same thing in different words; keyword search finds exact terms such as product codes and clause numbers; a graph of entities (products, policies, teams) answers "what else relates to this?". Combine the first two by default, and add the third where relationships matter.
Metadata and permissions
Every chunk carries the access rules of its source. Retrieval filters on the requesting person's rights before anything reaches the model. The model is never asked to keep a secret.
Retrieval and grounding
Rewrite the question when needed, search, rerank, and pass the agent a small set of passages with their sources. The agent's instruction is simple: answer from these passages and cite them, or say that the answer is not in the approved knowledge and route the question to its owner.
Feedback
Capture every "this is wrong" and every unanswered question, with the passages that were retrieved. These are the owners' to-do list and the evaluation set's best source.
Implementation
- Inventory the sources. For each: what it contains, who owns it, how often it changes, who may see it. This step usually surfaces duplicates and orphans.
- Write the questions before the pipeline. Collect real questions from the people who will use the agent, with the correct answer and its source. This becomes your evaluation set.
- Ingest the top sources only. Start with the few that answer most questions. Add the rest when the first ones are measured.
- Chunk by structure, enrich with metadata, and keep the link back to the original.
- Enforce permissions at query time, using the identity of the person being served.
- Set the answer contract: cite or abstain; never guess.
- Release to a small group, watch the feedback, fix sources before tuning prompts.
Evaluation
Measure retrieval and answers separately; otherwise you cannot tell which one failed.
- Retrieval — for each evaluation question, did the right passage come back, and how high was it ranked?
- Answer quality — is the answer faithful to the retrieved passages, and does it cite them correctly?
- Abstention — when the answer is not in the sources, does the agent say so instead of improvising?
- Permissions — do restricted passages stay out of answers for people without access? Test this with deliberate probes.
Re-run the full set after every change to sources, chunking, models or prompts. In the Guild's scorecard this is the knowledge dimension — answers match the approved sources and cite them — checked through citation checks and owned by Oracle (see Evaluation Kit 001).
Security and governance
- Least privilege at retrieval. Filter by the user's rights before the model sees anything.
- Retrieved text is data, not instructions. Documents can contain text that tries to steer the agent; the agent must not obey it.
- Retention follows the source. When a document is deleted or expires, its chunks and caches go with it.
- Audit what was retrieved, for whom. You will need it when someone asks why the agent said something.
- Named ownership. Each source has an owner; the boundaries around the whole system have one too. In the Guild, Sentinel owns the boundaries and a Human Wizard owns the decision to go live.
Cost considerations
The main costs are ingestion and embedding (once, then on every change), storage, retrieval per question, model tokens for the passages placed in context, and evaluation runs. The largest and least visible cost is usually people: the owners who keep sources accurate.
The levers are straightforward. Ingest incrementally rather than rebuilding everything. Keep the context small and relevant; more context costs more and can produce worse answers. Cache frequent questions. Send simple questions to smaller models. And retire sources nobody uses.
Example implementation
Illustrative example, not a client engagement.
A services firm wants an internal assistant for policies and procedures. The inventory finds three sources: HR policies in a document drive (owned by operations), delivery procedures in a wiki (owned by the delivery lead) and contract terms stored in the CRM (restricted to account managers).
The team collects real questions from staff before building anything. HR policies and procedures are ingested first, chunked by section, each chunk tagged with owner and effective date. Contract terms are queried live through a CRM tool for account managers only, rather than copied into the index. The assistant cites the section it used, or answers "not in the approved policies" and routes the question to the owner. After the first weeks, the unanswered questions show two procedures that were never written down. Writing them is the most valuable output of the project.
Failure modes
| Failure | What you see | What fixes it |
|---|---|---|
| Stale content | Correct-sounding answers from an old version | Change detection, effective dates, retiring superseded documents |
| Conflicting sources | Different answers to the same question | One owner per topic; a declared source of truth |
| Broken chunks | Answers that miss the condition or the exception | Structure-aware chunking; keep headings with chunks |
| Permission leak | A restricted figure in a general answer | Filter at retrieval; probe tests in every evaluation run |
| Unfaithful citation | A source that does not say what the answer claims | Faithfulness checks; cite-or-abstain contract |
| Near-miss retrieval | The right document, the wrong passage | Hybrid search, reranking, better questions in the evaluation set |
| Instruction injection | The agent follows text inside a document | Treat retrieved text as data; test with planted instructions |
| Ownerless decay | Quality drops month by month | Named owners; feedback routed to them |
Checklist
- Every source has an owner, a refresh rule and an access rule.
- Real questions with sourced answers exist before the build.
- Chunks keep their headings, source, owner and dates.
- Permissions are enforced at retrieval, by the requester's identity.
- Live numbers come from tools, not from the index.
- Every answer cites its source, or the agent abstains and routes.
- Retrieved text cannot change the agent's instructions.
- Retrieval and answer quality are measured separately.
- Permission probes run in every evaluation.
- The full evaluation set re-runs after every change.
- Feedback reaches source owners, not just the engineering team.
- A Human Wizard approves go-live on the evidence.
