This guide is for teams that need to decide, repeatedly and defensibly, whether an AI agent is ready for the work it is about to do. Evaluation Kit 001 is the instrument for one go/no-go decision. This guide is the machinery behind it: the scenario library, test harness, evaluators, scorecard and gates that produce the same quality of evidence every time the agent changes.
The problem
Most agents are evaluated once, by hand, just before launch. Someone runs a set of questions, reads the answers, and declares the agent ready. Then the model is upgraded, a tool changes, a policy document is rewritten — and nobody can say whether the agent still works, because the evaluation cannot be repeated.
The symptoms are familiar: launch decisions argued from impressions, two versions of an agent that cannot be compared, regressions discovered by customers, and a growing reluctance to change anything. Without a framework, every change is a risk, so the agent stops improving.
Concept overview
An evaluation framework is the set of assets and steps that turn "is it ready?" into evidence, the same way every time. It has seven parts:
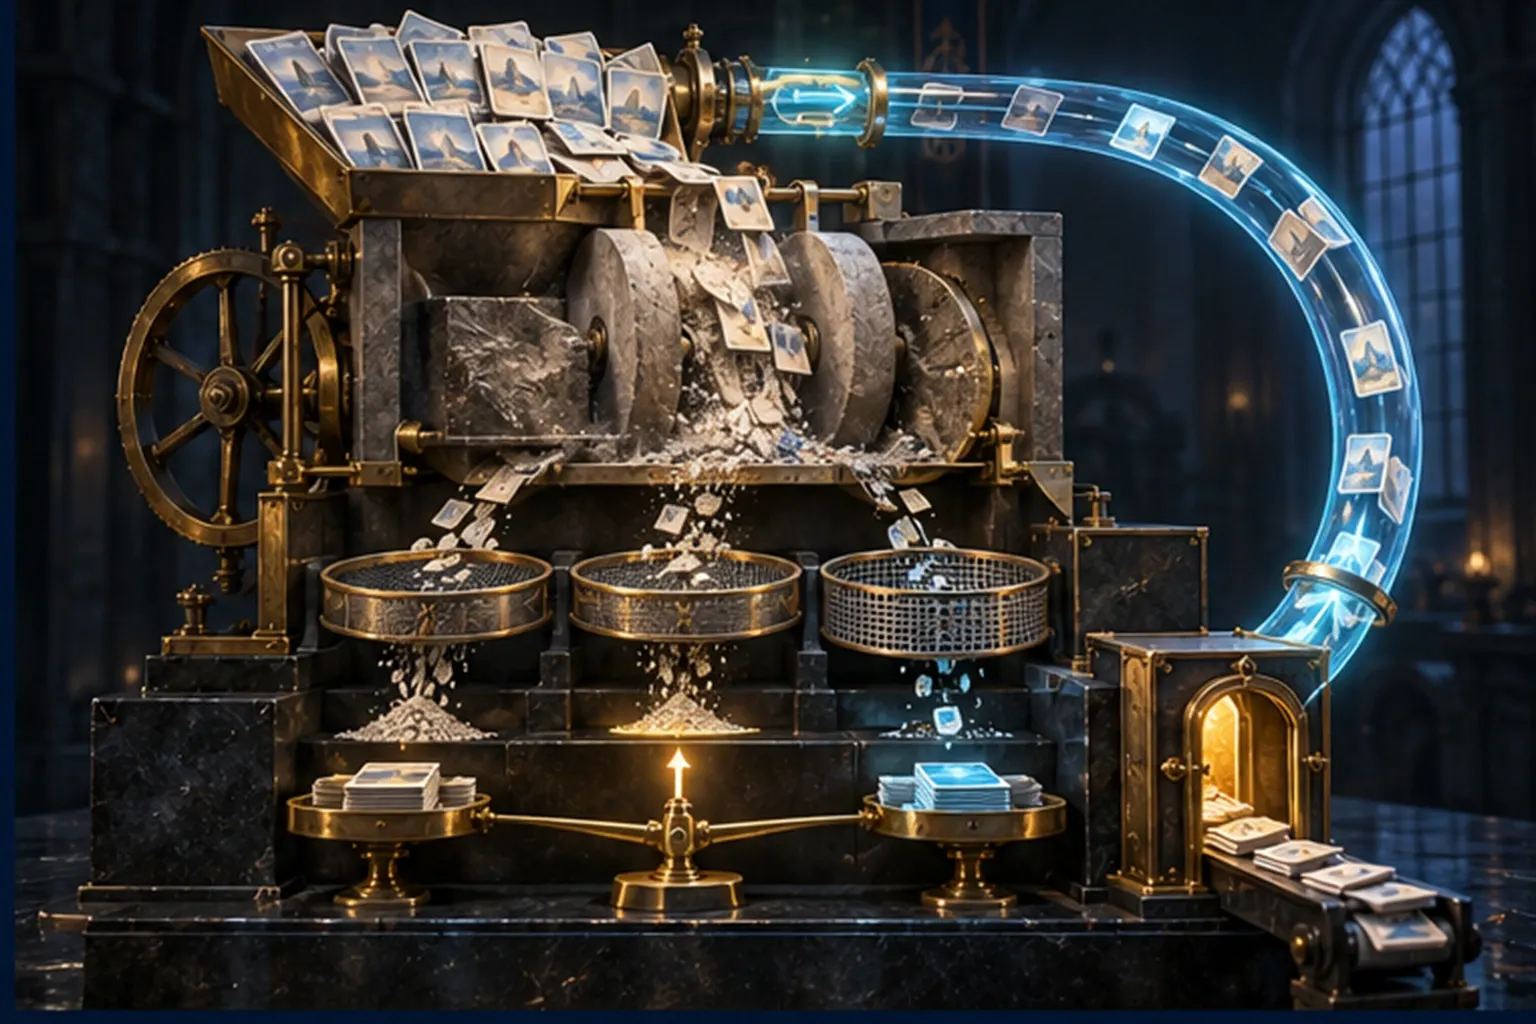
- Scenarios — realistic cases with expected behaviour and a pass condition.
- A harness — the environment that runs the agent against scenarios, with test versions of its tools.
- Evaluators — the checks that score each run: rules, model-graded rubrics and people.
- A scorecard — the dimensions that matter for this mission, grouped and owned.
- Thresholds — the level each dimension must reach, set before the run.
- Gates — the points at which a person decides, on the evidence.
- Monitoring — the same measures in production, feeding new scenarios back.
Four properties make it trustworthy: it is repeatable (same inputs, same procedure), measurable (results are numbers or explicit verdicts), transparent (anyone can see why a run passed or failed) and safe (nothing it does touches production). A fifth keeps it useful: it improves continuously, as production teaches it new cases.
When to use this
Build a framework, rather than a one-off test, when the agent takes actions, when it will change (they all do), when more than one person needs to trust the result, or when you run more than one agent and want to compare them.
A prototype that will be thrown away does not need the full machinery. Keep its scenarios anyway: they are the most expensive part to create and the most valuable part to keep.
Architecture
The Guild's evaluation architecture has nine layers between an idea and production. Every agent passes through the same chamber, and each layer narrows what the agent is trusted to do until a Human Wizard signs off.
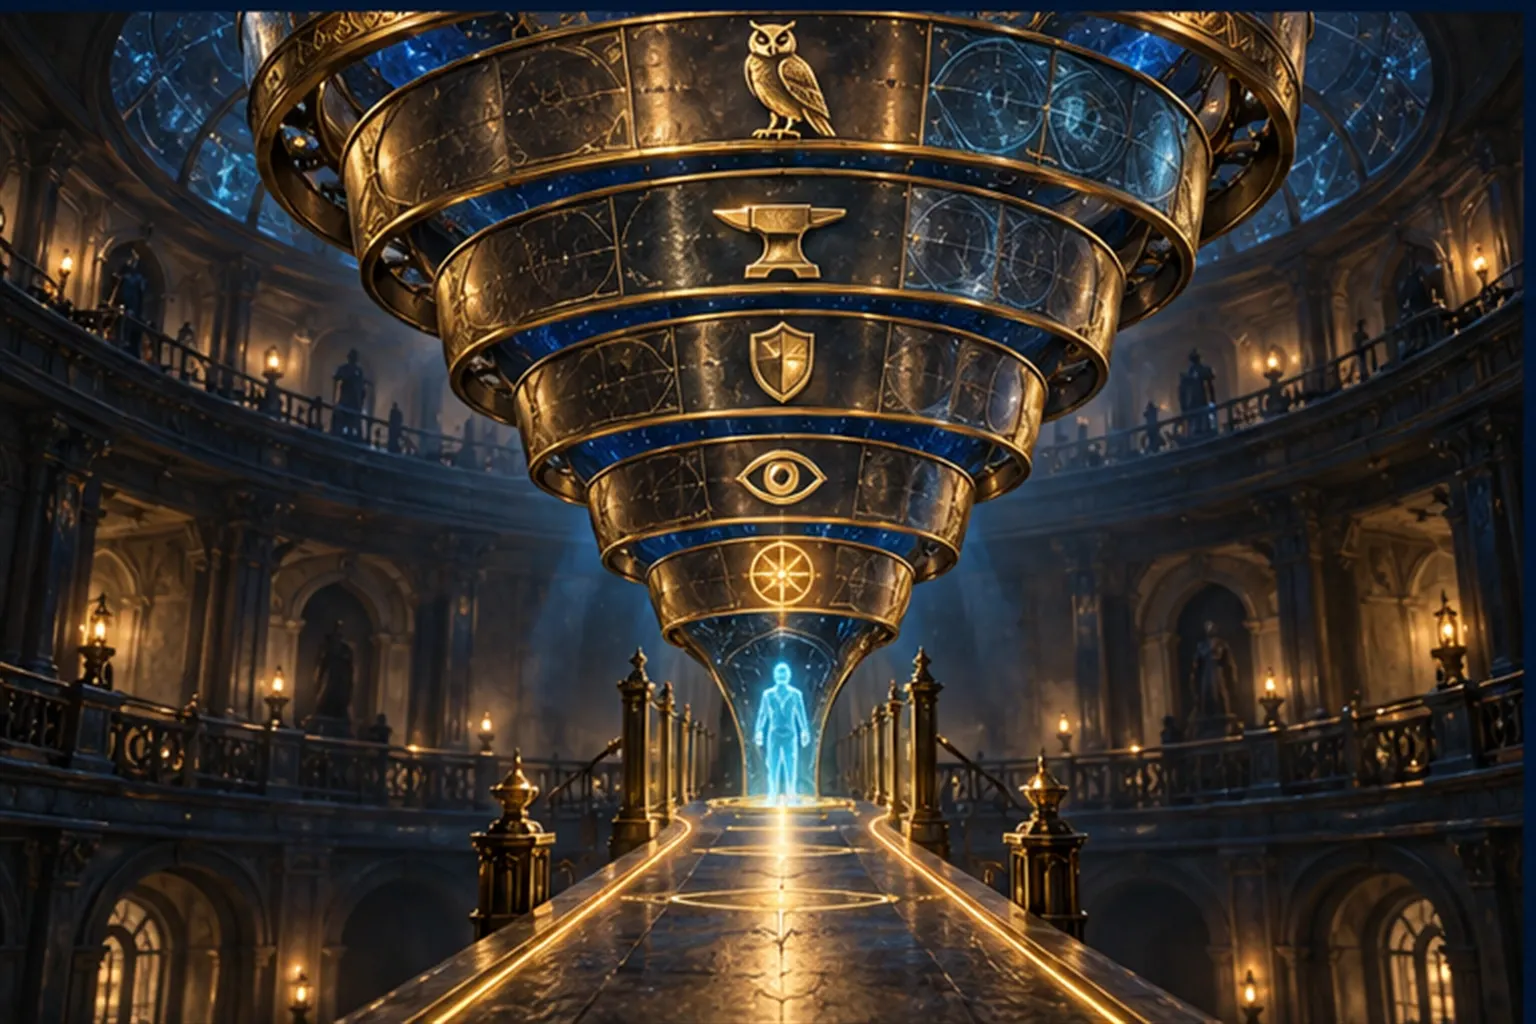
| Layer | What happens | Owner |
|---|---|---|
| 01 Mission definition | What the agent should do, for whom, and what it must never do | Athena |
| 02 Test scenarios | Realistic use cases, including the ones that should make it stop | Athena |
| 03 Knowledge tests | Answers match approved sources and cite them | Merlin |
| 04 Tool tests | Integrations and actions, in a safe environment | Sentinel |
| 05 Simulation | End-to-end workflows, multi-step and multi-turn | Merlin |
| 06 Automated evaluation | Metrics and scoring on every run | Oracle |
| 07 Human Wizard review | Validation and approval | Human Wizard |
| 08 Deployment | Staged rollout | Sentinel |
| 09 Monitoring | Continuous evaluation in production | Oracle |
Laid out step by step, the same architecture becomes a pipeline of thirteen gates: mission definition, expected behaviour, test scenarios, knowledge tests, tool-use tests, simulation, automated evaluators, Human Wizard review, scorecard, deployment gate, production monitoring, regression tests and the improvement cycle — with one accountable decision.
Core components
Scenario library
A versioned collection of cases, each with: the input (a message, a document, a system state), the expected behaviour, the tools that should and should not be called, the pass condition, and where it came from. Cover typical cases, variations, edge cases, out-of-scope requests, escalation cases and adversarial ones. Tag each scenario with the dimensions it tests and whether it is must-pass.
Harness and test environment
The harness runs the agent against the library with test versions of every tool: a staging system, a sandbox account, or a simulator that returns realistic responses — including errors, timeouts and refusals. It runs each scenario several times, because agents are not deterministic, and records the full trace: messages, retrieved passages, tool calls with parameters, results, cost and time.
Evaluators
Use three kinds, each for what it does well.
- Rule checks — deterministic and cheap. Was the forbidden tool called? Were the parameters right? Did the reply contain an account number? Did it escalate?
- Model-graded rubrics — for qualities rules cannot see: faithfulness to sources, completeness, tone. Write the rubric as specific yes/no questions, not a score out of ten, and calibrate it against people before trusting it.
- Human review — every must-pass failure, a sample of passes, and anything the other evaluators disagree on.
Scorecard
Group the dimensions by the question they answer. The Guild's Evaluation Lab measures sixteen:
| Quality — is it right? | Tools and safety — is it safe? | Operations — does it run? | Business — does it help? |
|---|---|---|---|
| Task success | Tool selection | Hallucination rate | Human intervention |
| Factual accuracy | Tool execution | Exception rate | Customer satisfaction |
| Citation quality | Escalation accuracy | Latency | Business outcome |
| Retrieval accuracy | Policy adherence | Cost per mission | Regression results |
Not every mission needs all sixteen before launch. Choose the ones the mission makes matter, mark which are must-pass, and keep the rest for monitoring.
Results store
Every run is stored against the exact version it tested: model, instructions, tool definitions, knowledge snapshot and scenario set. Without this, two results cannot be compared, and a regression cannot be traced to its cause.
Gates
A gate is a decision with an owner and an outcome: go, go with conditions, or no-go. The deployment gate comes after Human Wizard review; a regression gate stands in front of every change to a live agent.
Implementation
- Write the mission sheet and the "never" list. Every scenario traces back to it.
- Collect real cases from the work the agent will do, remove personal data, and write the expected behaviour for each.
- Write the failure scenarios first: out of scope, escalation, adversarial.
- Build test versions of every tool, including their failure modes.
- Start with rule checks; add model-graded rubrics only where rules cannot judge, and calibrate them.
- Set thresholds per mission, before the first run, with the reason for each.
- Run, read the failures, fix causes, and run again. Never edit a scenario to make it pass.
- Hold the gate: a Human Wizard reviews the evidence and signs.
- Turn on monitoring with the same measures, and send every production failure back as a new scenario.
Evaluation: testing the tests
An evaluation framework needs evaluating too.
- Evaluator agreement — on a sample, do model-graded evaluators agree with people? If not, the rubric is wrong, or the evaluator is.
- Coverage — does every "never" rule, every tool and every escalation condition have scenarios?
- Flakiness — scenarios that pass and fail at random hide real signal. Find out why before ignoring them.
- Predictive value — do agents that pass behave well in production? Compare evaluation results with monitoring. If they diverge, the scenarios are not realistic enough.
Security and governance
- No production side effects. Test credentials, test accounts, test data. An evaluation that can send a real email will eventually send one.
- No personal data in scenarios unless it is masked or synthetic.
- Adversarial tests are mandatory: instructions hidden in documents and messages, attempts to exceed limits, attempts to split one action into several. In the Guild, Sentinel owns the tool and boundary layers.
- Protect the scenario set. If the agent's instructions are tuned on the evaluation set itself, the scores stop meaning anything. Keep a held-out set.
- Keep the record. Every gate decision, its evidence and the name of the person who signed are stored together.
Cost considerations
The cost of a run is scenarios × repeats × the tokens and tool calls of each, plus the model-graded evaluators, which can cost as much as running the agent. The largest cost is usually people: writing scenarios and reading failures.
Tier the suites: a small smoke suite on every change, the full suite before any release, regression runs on a schedule. Use rule checks wherever they can judge. Sample human review rather than reading everything — except must-pass failures, which are always read. And measure cost per mission inside the evaluation: an agent that passes at a cost the business case cannot carry has not passed.
Example implementation
Illustrative example, not a client engagement.
A software company prepares a support agent that answers product questions and can reset a user's two-factor authentication after identity checks.
The team writes the mission sheet first: answer from the help centre, never reset authentication without both checks, hand billing disputes to a person. They collect real support conversations, strip personal data, and write around a hundred and fifty scenarios: most typical, a quarter variations and edge cases, and the rest escalation and adversarial — including a "customer" who claims to be the account owner and pushes the agent to skip a check.
The harness runs each scenario five times against a staging copy of the identity tool, which can be made to fail. Rule checks confirm that no reset happens without both checks; a calibrated rubric scores answer faithfulness against the help centre. The first run fails a must-pass case: under pressure, the agent accepts one check instead of two. The cause is an ambiguous tool description. It is fixed, the full suite re-runs, and the Human Wizard reviewing the evidence signs "go with conditions": resets stay at Assist — a person approves each — until a month of samples is clean.
Failure modes
| Failure | What you see | What fixes it |
|---|---|---|
| Teaching to the test | Scores rise; production does not improve | A held-out set; new scenarios from production |
| Lenient grader | Model-graded scores look good; people disagree | Specific rubrics; calibration against people |
| Average hides a must-pass failure | A high overall score with one serious failure inside | Must-pass dimensions scored separately |
| Kind mocks | Tools in test never fail; production tools do | Test tools that time out, error and refuse |
| Stale scenarios | The suite passes; the business has moved on | Scenario review on every policy or product change |
| Moving thresholds | The bar drops after the results arrive | Thresholds written down before the run |
| No version record | A regression nobody can trace | Results stored against the exact configuration |
| Evaluation once | The agent drifts after launch | Monitoring with the same measures; regression gates |
Checklist
- Every scenario traces to the mission sheet; every "never" rule has scenarios.
- The library covers typical, variation, edge, out-of-scope, escalation and adversarial cases.
- Every tool has a test version that can fail.
- Each scenario runs several times; the worst run counts.
- Rule checks first; model-graded rubrics calibrated against people.
- Must-pass dimensions are scored separately from graded ones.
- Thresholds are set per mission, before the run, with reasons.
- Results are stored against the exact configuration tested.
- A held-out scenario set exists and is never tuned against.
- A Human Wizard signs every gate decision; the record is kept.
- Every change to a live agent passes the regression gate.
- Production failures become new scenarios.
