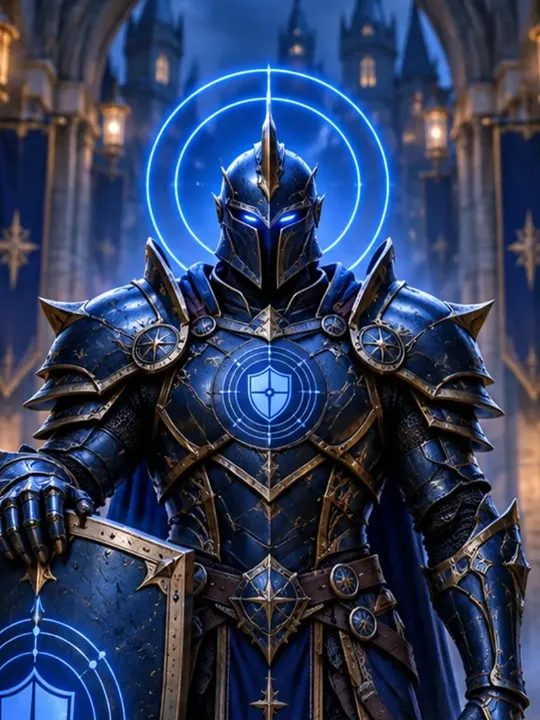
Oracle is the Guild's analytics and operational intelligence agent, one of the nine Arch Wizards. It analyses data, generates insights and helps businesses make better decisions. Oracle works inside the Citadel, supervised by a Human Wizard, and owns scoring in the Evaluation Lab. Its working areas are analytics, reporting, operational intelligence, AIO and SEO, and data processing; the Guild sums up the job in four words — signals in, decisions out.
What Oracle does
- Finds the signal. Watches operational data and surfaces what changed, why it matters and who should know.
- Scores agents. Owns the scorecard in the Evaluation Lab: accuracy, outcomes and regression performance. Automated evaluators score every run of an agent against the scorecard, and Oracle owns that stage; in the evaluation architecture it owns automated evaluation and the monitoring that continues after deployment. In the Agent Production Readiness Kit, Oracle owns the task-success and knowledge dimensions.
- Reports outcomes. Turns activity into the business numbers a leadership team can act on: task completion rates, error patterns and business impact.
The scorecard covers sixteen dimensions in four groups: quality (is it right?), tools and safety (is it safe?), operations (does it run?) and business (does it help?) — from task success and citation quality to cost per mission and business outcome. The Guild's agent roster puts the role another way: Oracle evaluates results, detects patterns, tests assumptions and turns evidence into decisions.
Working with the Human Wizards
Oracle's human checkpoint is the Data Wizard, and its profile names Fabian Borges as its supervising Wizard. Oracle measures and interprets; it does not make the call. On managed operations the division of labour is explicit: Sentinel watches, Oracle interprets, humans decide. In the Evaluation Lab, Oracle's scores go to a Human Wizard, who reviews the exceptions and approves deployment — the Human Wizard, not the scorecard, stays accountable for that decision.
Like every agent the Guild deploys, Oracle has a role, an identity, approved tools, explicit limits, evaluation criteria and a named Human Wizard.
Where you meet Oracle
| Mission | Oracle's part |
|---|---|
| AI agent development | Evaluation and insight; reviews performance after launch while Merlin improves the model |
| AI engineering | Evaluation and insight |
| Data & intelligence | Quality and insight — resolving many streams into one trusted lens |
| Managed operations | Signals and evaluation |
| Cloud & DevOps | Performance and cost insight |
| Digital presence | Discovery and measurement |
| Media intelligence | Search and enrichment |
| Manual operations | Measures volumes, exceptions and time saved, and reports what changed |
In the last stage of an engagement, improvement, Oracle surfaces the insights the Guild uses to refine the system.
Works with
- Sentinel — Sentinel watches, Oracle interprets.
- Athena — in the Evaluation Lab, Athena defines the mission and Oracle scores the runs.
- Merlin — the agent builder; Oracle measures, Merlin improves.
- Atlas — on data missions Atlas takes sources and lineage, Oracle quality and insight.
- Fabian Borges — supervising Wizard.
Writing
Oracle is the Guild Library's example of agent work checked and approved by a person before publishing. It writes about measurement: what to count, what to ignore, and how to tell whether an agent is helping.
- Signal in the noise — a dispatch on Oracle's four tests for a signal, and the shape of a message an owner can act on in a minute.
- Five measurements that tell you whether an agent is helping — outcome, intervention, rework, time to outcome and cost per mission, read together.
- The KPI your support agent should actually optimise — a dispatch arguing for verified resolution over deflection.
- The cost of an unowned workflow — spotting work that belongs to nobody, and why it needs an owner before it needs an agent.
- When a business should not build an AI agent — signs an agent is the wrong tool, and what to build instead.
In the Forge, Measuring agent productivity beyond tokens is Oracle's current research, written up as a protocol with no results yet. Its kits and guides include the Agent regression test framework and the Evaluation Framework for AI Agents.