A growing company's digital operations usually run on alarm. Something breaks, a customer notices, the one person who understands that system drops what they are doing, and the fix is applied under pressure. Then it happens again. This playbook describes the minimum system that replaces alarm with calm: an inventory, an owner for everything, a few signals that matter, a defined response, safe change and a regular review. None of it needs a large team or expensive tools.
The problem: operations by alarm
Systems were added one at a time as the business grew: a website, a shop, a CRM, an accounting package, a few integrations, some cloud services, perhaps an AI assistant or two. Each was set up by whoever needed it. Nobody has a complete list. Monitoring, if it exists, sends alerts to an inbox nobody reads. Changes are made directly in production because that is quicker. Backups are assumed to work.
The result is a business that discovers problems from its customers, depends on the memory of one or two people, and spends its best engineering time on maintenance and firefighting instead of improvement.
Concept: calm by design
A calm operation is not one where nothing goes wrong. It is one where, when something goes wrong, everyone knows whose it is, the problem is seen before customers see it, the response is already written down, and the cause is fixed rather than patched.
Calm comes from three things defined in advance for every system: an owner, a signal and a response. Everything else in this playbook supports those three.
When you need it
You need this playbook if any of these sound familiar:
- incidents are found by customers more often than by monitoring;
- nobody can say with confidence what is running, who has access to it, or where the data lives;
- one person is the only one who can fix a critical system;
- changes regularly break something unrelated;
- vendors are many and nobody coordinates them;
- you have never tested restoring from a backup.
Architecture: the minimum system
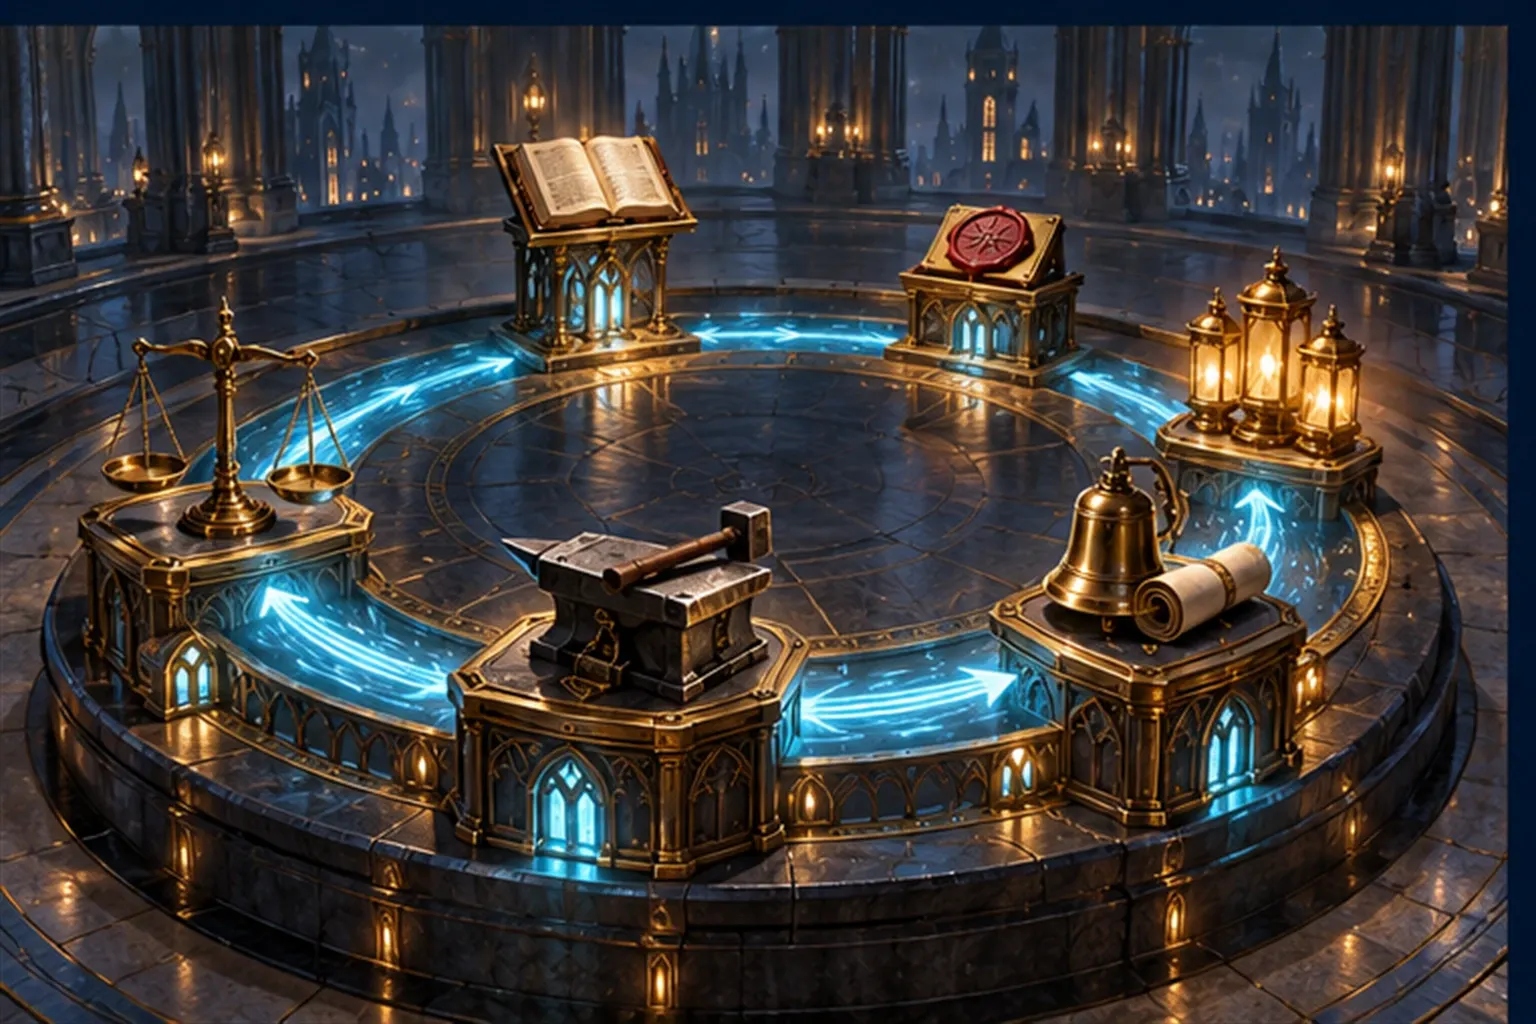
- Inventory — what you run, where, and what depends on what.
- Ownership — one named owner, and a backup, for every system.
- Signals — a short list of measures that tell you when something needs attention.
- Response — severity levels, escalation paths and runbooks for the common failures.
- Change — every change has an owner, a reason, a test and a way back.
- Review — a regular look at the evidence, and deliberate improvement.
Components
1. An inventory you trust
One list, kept current, with a row for every system: what it does, who owns it, which vendor provides it, where it is hosted, what data it holds, what it depends on, who has administrative access, and what it costs. Start with the systems customers touch and the systems money passes through. A spreadsheet is fine; an out-of-date diagram is not.
2. An owner for everything
Every system, integration and automation has one named owner and one backup. The owner does not have to fix everything personally. They are responsible for knowing its state, approving changes and making sure problems are resolved.
3. A small set of signals
Watch fewer things, and act on all of them. For most growing companies the minimum is:
- availability and error rates of customer-facing systems;
- response time for the critical journeys — sign-in, checkout, booking, enquiry;
- backup success, and the date of the last successful restore test;
- certificate and domain expiry dates;
- outstanding security updates for critical systems;
- monthly cost against budget;
- for AI agents: exception rate, human intervention rate and cost per completed task.
Every signal has an owner and a threshold. An alert should mean a person must act; a signal nobody acts on should be removed, not ignored.
4. A defined response
Agree three severity levels in plain words — "customers cannot buy", "something is degraded", "something needs attention this week" — and who is told for each. Write a one-page runbook for each of the five most likely failures: what to check first, how to roll back, who to call at the vendor. Record every incident in one place, with its cause and the change made because of it.
5. Safe change
Google's SRE book attributes most outages to changes in a live system, and the remedy it gives is plain: roll out gradually, detect problems quickly, and roll back safely. For a growing company that means every change has an owner, a reason, a test and a rollback. Make changes small. Avoid changing critical systems just before a weekend or a busy period. Keep a change log, even a simple one: when something breaks, the first question is always "what changed?".
6. A regular review
Thirty minutes a week: the incidents, the signals that fired, the changes made, and anything on the inventory without an owner. Once a month, look at trends, cost and access. This is the meeting where the system improves rather than just survives.
Where agents fit
AI agents suit the watchful parts of operations: checking signals continuously, correlating an alert with recent changes, gathering the evidence a person needs, drafting the incident record and the status update. In the Guild's managed operations the division is stated plainly: "Sentinel watches. Oracle interprets. Humans decide."
The boundary matters. An agent may observe, investigate and prepare. Changes to production, to access rights and to anything a customer will see are approved by the system's owner until the agent has earned a wider boundary on evidence. An agent that can change production unsupervised is a new source of incidents, not a cure for them.
Implementation: the first month
- Week one — build the inventory and name owners and backups. Remove access for people who have left.
- Week two — choose the signals, set thresholds, and send alerts to people rather than shared inboxes.
- Week three — write the severity levels and the five runbooks. Test one backup restore.
- Week four — start the change log and hold the first weekly review.
After a month the system is not finished, but it exists. Each week's review makes it better.
Failure modes
- Alert fatigue. Too many alerts, so none are read. Cut signals until every one is acted on.
- Monitoring without owners. Alerts that go to everyone go to no one.
- Heroics. One person who fixes everything, and a business that stops when they are away.
- Untested backups. Discovered to be broken during the incident that needs them.
- Silent changes. Changes made without a record, so every incident starts with an investigation.
- Agents without boundaries. Automated fixes applied to production without approval.
Evaluation: how you know it is calm
- the share of incidents found by monitoring rather than by customers;
- time from signal to acknowledgement, and to resolution;
- the share of changes that needed a fix or a rollback, and how long recovery took;
- alerts acted on versus alerts ignored;
- the date of the last successful restore test;
- the number of systems without an owner — the target is zero.
Security and governance
Calm operations and secure operations are mostly the same practices. Review administrative access monthly and remove what is not needed. Give people and agents the least privilege their role requires, and make access easy to revoke. Keep credentials out of shared documents. Offboard leavers on the day they leave. Keep a record of who changed what. Test backups, because a backup that cannot be restored is not a backup.
Cost considerations
The main cost of this playbook is time, not tools: a few days to set up, then an hour or two a week to run. Many monitoring needs can be met with what your existing platforms already provide. The cost of not doing it is harder to see — lost sales during outages, senior time spent firefighting, cloud spend nobody reviews — and easy to underestimate. Right-size the effort: monitor customer journeys and money first, and add more only when a real incident shows a gap.
Example
Illustrative example, not a client engagement.
A 40-person online retailer runs a shop platform, a payment provider, a CRM, an email tool, an accounting package and a handful of integrations, set up over several years by different contractors. After a weekend outage found by customers, the operations lead builds the inventory and finds two integrations nobody owns and several former contractors who still have administrative access.
Access is removed, owners are named, and alerts for checkout errors and failed payments go to the owner's phone instead of a shared inbox. The first restore test fails, so the backup configuration is fixed and the test repeated. From then on the weekly review asks the same questions: who found this week's incidents — the monitoring or a customer — what changed before each one, and is every system still owned?
Checklist
- There is one current inventory of systems, owners, vendors, data and access.
- Every system has a named owner and a backup.
- Signals cover customer journeys, backups, expiry dates, security updates and cost.
- Alerts go to people, not shared inboxes, and every alert is acted on.
- Severity levels and runbooks for the five most likely failures are written down.
- Every change has an owner, a reason, a test and a rollback, and is logged.
- A restore from backup has been tested in the last quarter.
- Access is reviewed monthly; leavers are removed on the day they leave.
- A weekly review looks at incidents, signals, changes and unowned systems.
- AI agents in operations investigate and prepare; owners approve changes.
